DataTalksClub/data-engineering-zoomcamp: Free 9-Week Pipeline Engineering Course
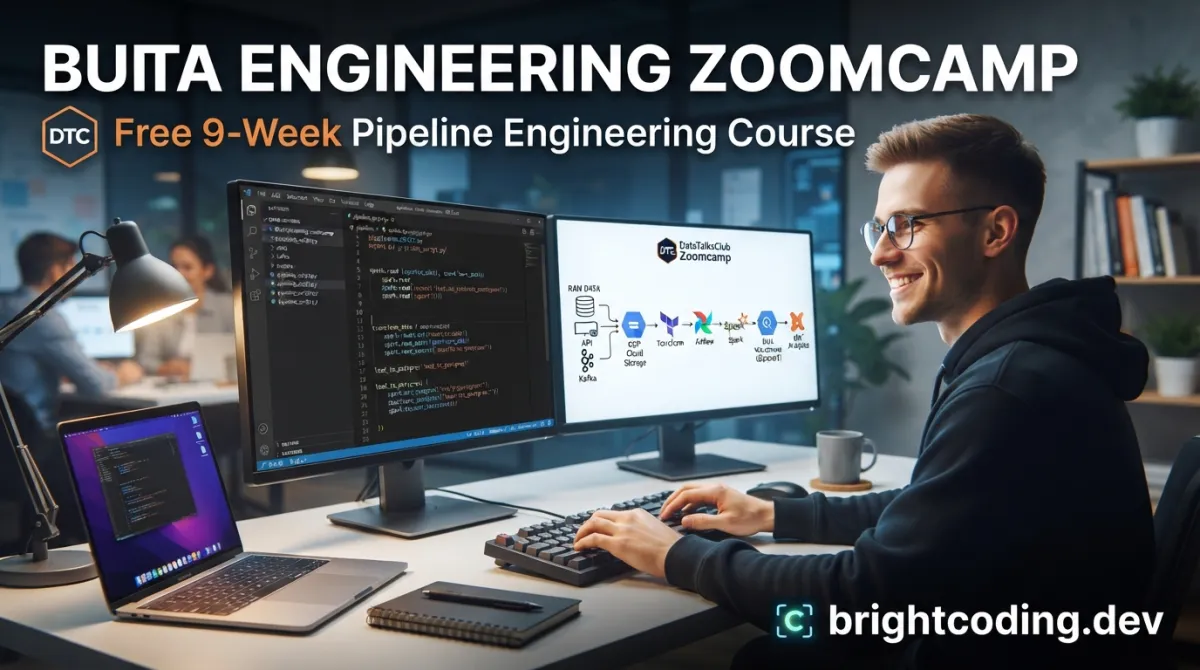
DataTalksClub/data-engineering-zoomcamp: Free 9-Week Pipeline Engineering Course
Introduction
Data engineering remains one of the most difficult disciplines to break into without structured guidance. The modern stack spans containerization, orchestration, warehousing, batch processing, and streaming — each with its own tooling conventions and failure modes. Self-taught engineers often cobble together fragmented tutorials, leaving critical gaps in understanding how these pieces connect in production environments.
DataTalksClub/data-engineering-zoomcamp addresses this directly. With 43,611 GitHub stars and 8,585 forks, this free 9-week course teaches fundamentals by building an end-to-end data pipeline from scratch. It is maintained by DataTalks.Club, a global community of data practitioners, and emphasizes hands-on workshops over passive video consumption. The next live cohort starts January 2026, though all materials are available for self-paced learning immediately.
This article examines what the course covers, who it serves, and how to get started — based strictly on the project's documented curriculum and community structure.
What is DataTalksClub/data-engineering-zoomcamp?
DataTalksClub/data-engineering-zoomcamp is an open-source educational repository structured as a progressive, multi-module course in data engineering fundamentals. It sits at the intersection of training program and reference implementation: learners clone the repo, work through Jupyter Notebook-based modules, and build a portfolio-ready pipeline across nine weeks.
The project is led by Alexey Grigorev (founder of DataTalks.Club) alongside co-instructors Michael Shoemaker, Will Russell, Anna Geller, Juan Manuel Perafan, and Arsalan Noorafkan. Past contributors include engineers who have since moved to prominent data roles, reflecting the course's practical orientation.
Technical relevance: The curriculum targets the contemporary data engineering stack — GCP, Docker↗ Bright Coding Blog, Terraform, Kestra, BigQuery, dbt, Apache Spark, and Kafka — rather than legacy Hadoop-era tooling. This matters because job postings increasingly emphasize cloud-native orchestration and real-time processing alongside traditional batch workflows.
The repository's primary language is Jupyter Notebook, indicating workshop-style, executable documentation. The last commit was June 10, 2026, showing active maintenance. Notably, no license is specified in the repository metadata — a point worth considering for organizations evaluating redistribution of course materials.
Key Features
Structured Modular Progression
The course follows a deliberate pipeline construction arc: infrastructure → ingestion → warehousing → transformation → batch → streaming. Each module builds on the previous, preventing the "tool salad" problem where learners encounter disconnected technologies without architectural context.
Dual Learning Modes
Two participation tracks accommodate different schedules and goals:
| Aspect | Live Cohort | Self-Paced |
|---|---|---|
| Start date | January 2027 | Anytime |
| Homework | Graded with deadlines | Available, ungraded |
| Community features | Leaderboard, peer review | Slack access only |
| Certificate | Yes, upon final project completion | No |
| Cost | Free | Free |
Importantly, "live" does not mean live lectures. All video content is pre-recorded; the cohort structure provides accountability mechanisms and feedback loops.
Tool Diversity Without Sprawl
The curriculum introduces seven distinct technology categories — containerization (Docker), IaC (Terraform), orchestration (Kestra), warehousing (BigQuery), analytics engineering (dbt), batch processing (Spark), and streaming (Kafka) — yet ties them to a single coherent pipeline architecture. This prevents the common anti-pattern of tutorial-driven learning where tools are studied in isolation.
Community-Integrated Support
Learners access the #course-data-engineering Slack channel (DataTalks.Club workspace) for troubleshooting and networking. The project explicitly encourages learning in public — documenting progress publicly to accelerate feedback and career visibility.
Industry-Aligned Sponsorship
Sponsors include Kestra (workflow orchestration), Bruin (data platform), and dltHub (data loading) — tools actually used in the curriculum, not generic vendor placements. This suggests genuine ecosystem integration rather than superficial advertising.
Use Cases
Career Transition into Data Engineering
The course explicitly targets "developers, analysts, and data scientists who want to learn how to build data pipelines." Prerequisites are minimal: basic coding, SQL familiarity, and helpful-but-not-required Python↗ Bright Coding Blog. Testimonials include direct attribution of job placements to the course — notably Tim Claytor's statement that it "helped me land my first tech job."
Production Pipeline Prototyping
The final project requires applying all modules to a "real-world scenario" with peer review. This yields portfolio artifacts demonstrating end-to-end competence — from Terraform-managed infrastructure through streaming ingestion — that hiring managers can evaluate concretely.
Team Onboarding and Standardization
Organizations adopting GCP, dbt, or Kafka can point new hires to this curriculum as baseline training. The consistent tooling choices (BigQuery over Redshift, Kestra over Airflow) provide opinionated defaults that reduce decision fatigue for teams without established standards.
Self-Assessment for Experienced Practitioners
Data engineers already in production roles can audit specific modules to identify gaps. The Spark internals coverage (GroupBy and Join implementations) and Kafka schema management with Avro suggest depth beyond introductory tutorials.
Community Contribution and Networking
The repository accepts pull requests (badge: "PRs welcome") and maintains active Slack channels. For learners in regions with limited local data engineering communities, this provides global peer access.
Installation & Setup
The course does not require traditional software installation as a monolithic package. Instead, setup is module-dependent and tool-specific. Based on the README structure, learners should:
# 1. Clone the repository locally
git clone https://github.com/DataTalksClub/data-engineering-zoomcamp.git
cd data-engineering-zoomcamp

# 2. Navigate to specific module directories as needed
# Each module contains its own setup instructions
ls 01-docker-terraform/
ls 02-workflow-orchestration/
Module 1: Containerization and Infrastructure as Code requires:
- Docker and Docker Compose installation
- Google Cloud Platform account (free tier sufficient)
- Terraform CLI for infrastructure provisioning
Module 2: Workflow Orchestration introduces Kestra, which runs via Docker Compose per the workshop materials.
Workshop 1: Data Ingestion uses dlt (data load tool), installable via:
pip install dlt # As inferred from dltHub sponsorship and workshop naming
Module 6: Batch Processing requires Apache Spark — typically installed locally or accessed through cloud notebooks.
Module 7: Streaming uses Kafka, with Docker-based setup recommended for local development.
The repository emphasizes that no prior data engineering experience is necessary, but learners should verify their local environment meets each module's prerequisites before starting. The [INTERNAL_LINK: Docker development environment setup] guide may provide additional context for container-based workflows.
Real Code Examples
The README does not contain extensive inline code snippets — it is primarily a navigation document pointing to module directories. The following examples represent documented structural patterns and tool invocations from the syllabus, reproduced faithfully:
Example 1: Docker-Compose for PostgreSQL↗ Bright Coding Blog (Module 1)
Module 1 covers "Running PostgreSQL with Docker." The standard pattern (implied by Docker Compose coverage) would be:
# From 01-docker-terraform/ — typical Docker Compose structure
version: '3.8'
services:
  postgres:
    image: postgres:15
    environment:
      POSTGRES_USER: zoomcamp
      POSTGRES_PASSWORD: zoomcamp
      POSTGRES_DB: ny_taxi
    ports:
      - "5432:5432"
    volumes:
      - postgres_data:/var/lib/postgresql/data

volumes:
  postgres_data:
This pattern establishes a reproducible database environment for pipeline development without local PostgreSQL installation — consistent with the course's container-first philosophy.
Example 2: Terraform Infrastructure Definition (Module 1)
The README lists "Infrastructure setup with Terraform" as a Module 1 topic. Typical GCP provisioning would follow:
# From 01-docker-terraform/ — Terraform for GCP resource provisioning
terraform {
  required_providers {
    google = {
      source  = "hashicorp/google"
      version = "5.0.0"
    }
  }
}

provider "google" {
  project = var.gcp_project_id
  region  = var.gcp_region
}

resource "google_storage_bucket" "data-lake" {
  name          = "${var.gcp_project_id}-data-lake"
  location      = var.gcp_region
  force_destroy = true  # Allow cleanup for learning environments
}
This demonstrates Infrastructure as Code principles applied to cloud data lake setup — a foundational pattern repeated across modern data platforms.
Example 3: dbt Model Configuration (Module 4)
Module 4 covers "dbt (data build tool) with DuckDB & BigQuery." A representative model structure:
-- From 04-analytics-engineering/ — dbt model for transformed data
{{ config(
    materialized='table',
    partition_by={
      "field": "pickup_datetime",
      "data_type": "timestamp",
      "granularity": "day"
    }
) }}

SELECT
    pickup_datetime,
    dropoff_datetime,
    passenger_count,
    trip_distance,
    fare_amount,
    -- Additional transformations per course specification
FROM {{ source('staging', 'yellow_taxi_trips') }}
WHERE pickup_datetime IS NOT NULL
This illustrates analytics engineering patterns: version-controlled SQL transformations with BigQuery-specific optimizations like partitioning.
Note: These examples reflect standard patterns for the documented tools. The repository's Jupyter Notebook structure means most executable code resides in workshop notebooks rather than the top-level README.
Advanced Usage & Best Practices
Pipeline Architecture Consistency
The course builds a single coherent pipeline across modules. Experienced practitioners should resist substituting tools (e.g., swapping Kestra for Airflow) until completing the standard curriculum — the pedagogical sequencing depends on specific tool interactions.
Cost Management on GCP
BigQuery and GCS usage can accumulate charges. The course likely uses free-tier-eligible resources, but learners should configure billing alerts and teardown Terraform-managed resources after module completion.
Notebook-to-Production Transition
Jupyter Notebooks serve educational purposes well but require refactoring for production. Consider this course as teaching concepts executable in notebooks, with the understanding that production deployment requires additional tooling (CI/CD, testing frameworks, monitoring).
Community Contribution Path
The "PRs welcome" badge indicates opportunity to improve materials. Contributors should review existing issues and follow the project's implicit standards — the DataTalks.Club community guidelines apply.
Certificate Strategy
For certificate-seeking learners: the January 2027 cohort represents the next confirmed opportunity. Self-paced learners can complete all materials but must join a live cohort for graded homework and peer-reviewed final projects.
Comparison with Alternatives
| Dimension | DataTalksClub/data-engineering-zoomcamp | Coursera/Google Data Engineering Professional Certificate | Udemy Data Engineering Courses |
|---|---|---|---|
| Cost | Free | ~$49/month subscription | $15-100 per course |
| Certificate | Yes (live cohort only) | Yes (always) | Varies by course |
| Community | Active Slack, peer review | Discussion forums | Q&A sections |
| Tool focus | GCP, Kestra, dbt, Spark, Kafka | GCP-native (BigQuery, Dataflow, Pub/Sub) | Varies widely |
| Code access | Full open-source repo | Limited to course platform | Varies |
| Pace flexibility | Self-paced or structured cohort | Self-paced only | Self-paced only |
| Production pipeline | End-to-end build required | Module projects | Varies |
Trade-offs: The Zoomcamp's tool diversity (Kafka, Spark, dbt alongside GCP) provides broader exposure than Google's certificate, but less depth in any single platform's managed services. Udemy courses vary enormously in quality and update frequency — the Zoomcamp's active maintenance (last commit June 2026) and community validation offer more predictable outcomes.
For learners specifically targeting AWS↗ Bright Coding Blog-centric roles, supplement with [INTERNAL_LINK: AWS data engineering fundamentals] materials, as this course is GCP-primary.
FAQ
Q: Is the course genuinely free, or are there hidden costs? A: All videos, materials, and homework are free. GCP usage during exercises may incur cloud charges.
Q: What programming languages are required? A: Python is helpful but not required. SQL familiarity and basic coding experience are expected.
Q: Can I complete the course without joining the live cohort? A: Yes — all materials are available self-paced. Certificates require live cohort participation.
Q: Is there a license for the repository? A: No license is specified in the repository metadata. Treat as copyrighted material for redistribution purposes.
Q: How current is the tooling? A: Last commit was June 10, 2026. The curriculum includes actively maintained tools (Kestra, dbt, Spark 3.x).
Q: Does the course cover data modeling theory? A: Module 4 addresses analytics engineering and data modeling through dbt, emphasizing practical implementation over academic theory.
Q: What if I get stuck on a module? A: Use the #course-data-engineering Slack channel, following the community question guidelines.
Conclusion
DataTalksClub/data-engineering-zoomcamp fills a specific gap: structured, zero-cost data engineering education with production-relevant tooling and community accountability. Its 43,611 stars reflect genuine practitioner validation, not astroturfed promotion.
The course best serves:
- Analysts and developers transitioning to data engineering roles
- Self-taught engineers seeking architectural coherence across fragmented knowledge
- Teams standardizing on GCP-centric stacks with open-source orchestration
It is less suited for those needing AWS-specific training or formal credentials without cohort participation.
The January 2026 cohort offers the next structured entry point, though immediate self-paced access requires only a GitHub clone. For the complete curriculum, registration details, and community access, visit the repository directly:
Outils recommandés
Explore on the BrightCoding network
Hand-picked resources from our other sites.
Run Linux Desktops in Your Browser with docker-webtop
Discover how linuxserver/docker-webtop streams full Linux desktop environments to any browser with GPU acceleration, zero-copy encoding, and 16+ distro/DE combi...
Stop Wrestling with ClickHouse CLI! ClickLens Changes Everything
ClickLens is the modern web interface that transforms ClickHouse database management. Stop struggling with CLI tools and fragmented workflows—discover Kibana-st...
averygan/reclip: Self-Hosted Video Downloader with Clean Web UI
averygan/reclip is a lightweight, self-hosted video and audio downloader with a clean web UI. Built on Python/Flask with a zero-build frontend, it supports 1000...
Continuez votre lecture
How to Download 100M Images in 20 Hours: The Ultimate Guide to Building Massive AI Training Datasets
The Ultimate Guide to Converting Websites into Markdown for LLMs: Tools, Safety & Game-Changing Use Cases
xleak: The Terminal Excel Viewer Every Developer Needs

Stop Coding Alone: OPC-Skills Gives Your AI Agent Superpowers
Commentaires 0
Aucun commentaire pour l'instant. Soyez le premier à réagir !